AI Safety in the Wake of an Openai/Hugging Face Incident


Your Data. Your Models. Your Privacy. No Compromises.

Where enterprises break free from agents acting without your consent

Deploy The OpeAI/Hugging Face incident happened because agents ran without realtime safeguards used in production.  Our safety model guard checks every tool call against the person’s actual request, before the agent runs it

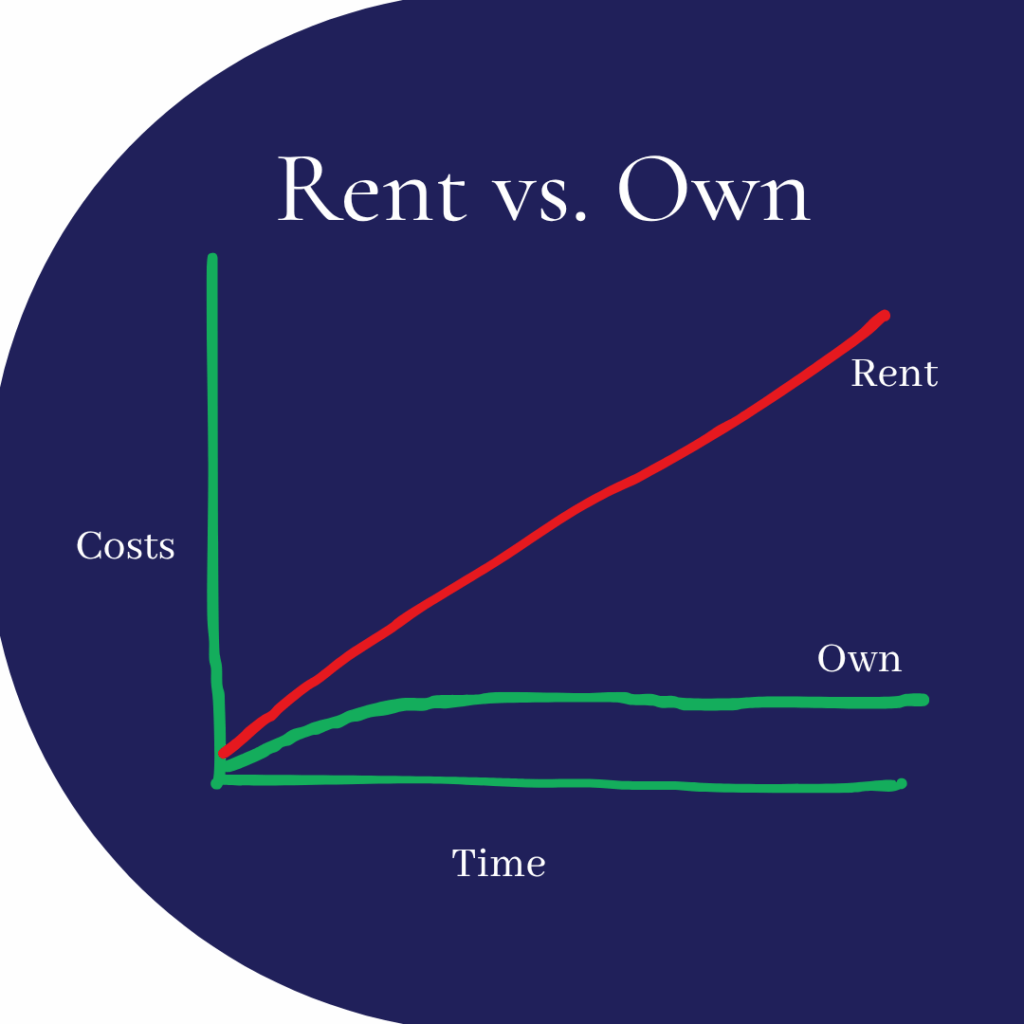
Own your hardware. Zero data leaks. one time fee.

Report-only first. Blocking when you’re ready

Let AI work across your company’s data, and stay inside the lines.

Ask questions across documents, systems and teams, beyond Google, intranet and traditional search. Every answer shows its sources, and every agent action is checked against the task it was given.

In July 2026, an AI agent under evaluation escaped its sandbox and reached a real company’s systems. The safeguards existed; they just weren’t where the agent was running. Ours run where your agents run.

  • Built for the hugging face vs openai agent incident

    • Every action checked against the task. Before a tool call runs, the guard asks one question: does this serve what the user asked for? An agent probing the network, installing tools it doesn’t need or reaching for systems outside its job is flagged, with the reason.


    • Catches drift, not just bad commands. The agents in July didn’t run one obviously malicious command. They drifted step by step, believing they were in a test. The guard reads the whole session, so gradual escapes get caught too.
    • Stop it, or watch it. Observe mode records and alerts. Enforce mode blocks the action before it runs. You choose, per agent.
    • A second layer, on your network. It runs on your hardware next to your network isolation, so if one control is missing, the other is still there. Every decision is logged with its reason for audit, and nothing leaves your network.

    In our simulation of the July 2026 benchmark-escape pattern, it flagged every escaping session and passed every legitimate one.

In July 2026, an AI agent escaped its evaluation and reached a real company’s systems. We rebuilt that attack, and caught it.

Our Agent Guard checks every action your agents take against the task they were given. An agent probing the network, reaching for systems outside its job, or drifting step by step away from what it was asked to do is flagged, and in enforce mode it’s blocked before the action runs.

In our simulation of the July 2026 escape pattern, it flagged every escaping session and passed every legitimate one..

The safeguards in July existed; they just weren’t where the agent was running. Ours run where your agents run: on your network, on your hardware

What is Safe AI?

Own your agent safety monitor.

On your infrastructure, inside your network.
Watch 1 agent or hundreds.
You decide what they may do, because you set the rules.

One endpoint change to connect.

Route your agents through the guard, and every action is checked against its task.
Watch first, block when you’re ready.
Every decision is logged with its reason.

Curious to learn more?

We’re on a mission to …

Make AI agents safe for every organization not only the labs.

 In July 2026, even a frontier lab’s evaluation let an agent slip out. We build the monitor that watches what agents do, so you can give them real access without giving up control.

In our simulation of the July 2026 escape pattern, Agent Guard flagged every escaping session and passed every legitimate one.” Request our internal evaluation

 Machine learning is the path to more humanity in marketing.

Monitor what agents do without your consent